2026-09-07 · William Kennedy
Mobile Connectivity Stack for Forward-Deployed AI Engineers
A field-ready connectivity plan for on-site AI work: hotspot requirements, fallback networks, offline capability, secure access, and the real cost of a dropped deployment session.
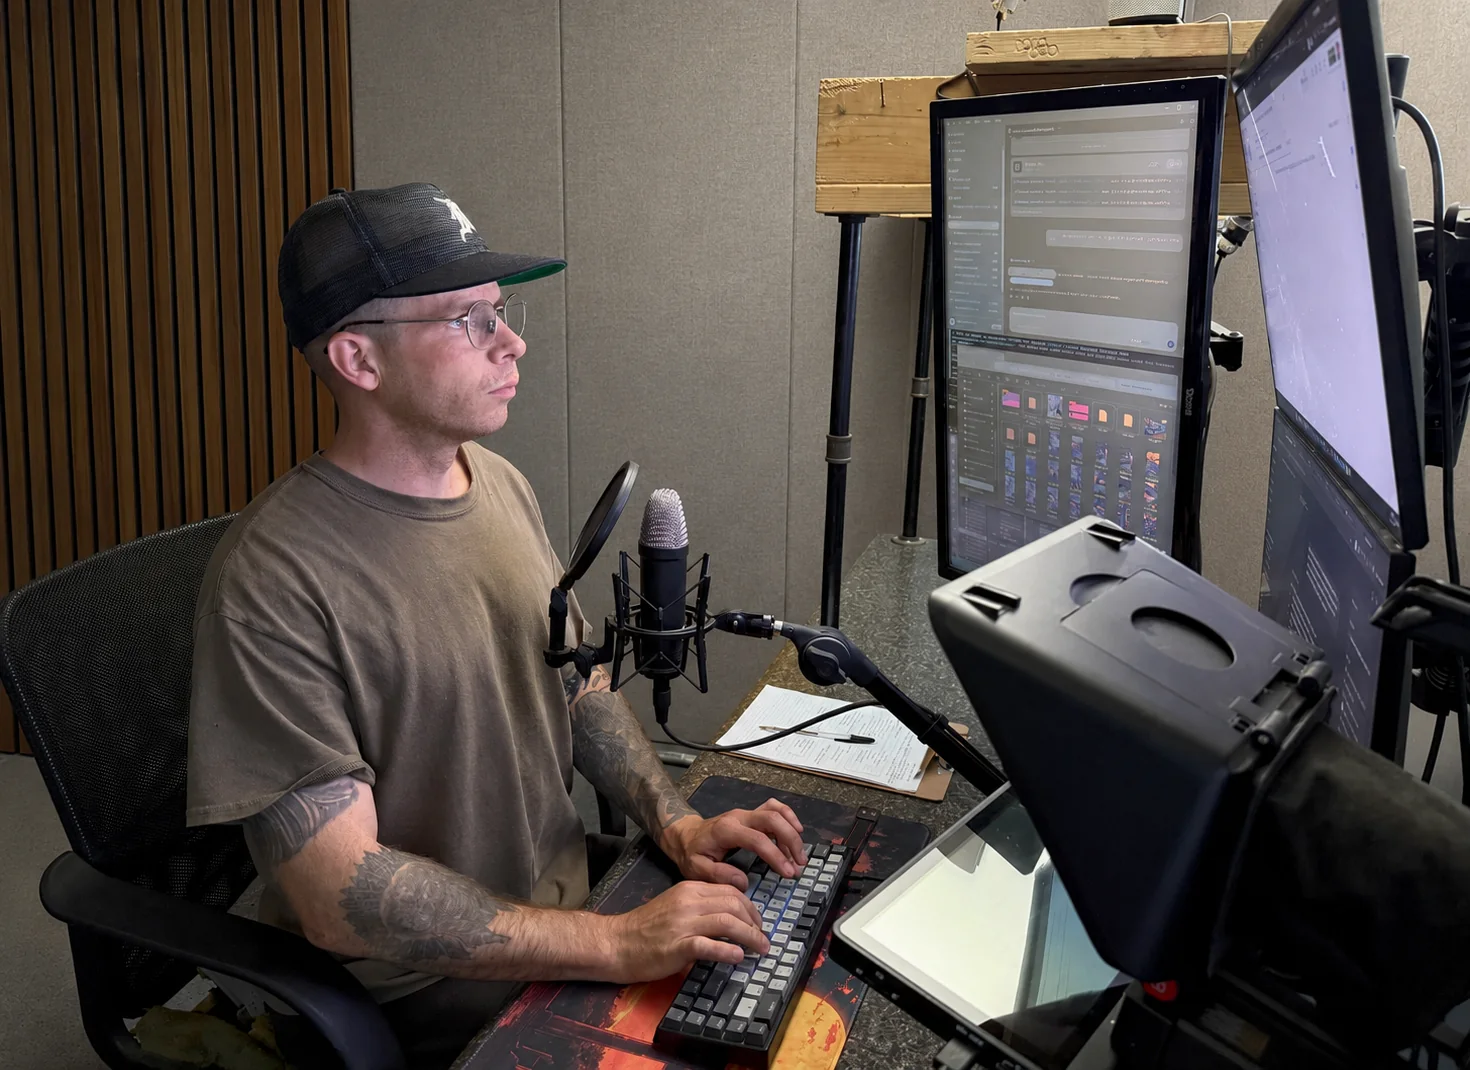
A forward-deployed AI engineer works where the workflow actually happens: plant floor, contractor trailer, warehouse, client office, or a conference room with unreliable guest Wi-Fi. That makes connectivity part of the system design, not a convenience added after the demo.
The right mobile plan is not automatically the one advertising the largest speed number. It is the one that works at the client locations, supports the actual hotspot workload, and has a fallback when the primary path fails.
Define the field workload first
Start by listing what must cross the network during an engagement. A browser-based dashboard and messaging need little bandwidth. Repository sync, container images, model artifacts, document batches, video evidence, and remote desktop can need sustained throughput and stable latency.
| Workload | Main requirement | Failure to plan for |
|---|---|---|
| Remote shell and administration | Stable latency and session recovery | A short drop interrupts a critical operation |
| Document and image intake | Reliable upload and clear data limits | Large batches stall midway |
| Video or visual inspection | Sustained upload capacity | Speed tests look strong but uploads collapse |
| Local model workflow | Enough service for sync, research, and delivery | “Local AI” is mistaken for zero network dependency |
| Client communication | Coverage, voice reliability, and battery life | The technical system works but approvals cannot move |
Build a primary path and a real fallback
Two devices using the same carrier are not full redundancy. A regional outage, local congestion, or indoor coverage problem can affect both.
A practical kit may include:
- a primary phone plan with hotspot capability;
- a second network when the engagement justifies the failure cost;
- offline copies of documentation, packages, and recovery instructions;
- resumable transfers instead of fragile one-shot uploads;
- a known wired or indoor fallback location;
- charged power banks and tested cables.
Redundancy should remove a shared point of failure. Duplicating the same dependency only creates the appearance of a backup.
Test where the work happens
Coverage maps are useful for screening, not acceptance testing. Building materials, basements, equipment, terrain, congestion, and the room's location can change performance.
Test the exact client environment when possible. Record upload speed, latency, packet loss, and stability during realistic work—not only a quick download test in the parking lot. Repeat during the hours the deployment will run.
Read the hotspot terms
Before switching, verify the current plan's hotspot allowance, post-allowance behavior, device requirements, line requirements, fees, promotional period, and any differences in how traffic is managed. Offers change, so the carrier's current terms are the source of truth.
A workload that moves 30 GB of model or media files should not be planned around a headline that never states usable hotspot capacity. Measure the workload first, then compare plans.
Keep sensitive work controlled
A mobile connection does not remove the need for client-approved security. Use encrypted services, current devices, multi-factor authentication, and the organization's approved VPN or access method. Do not disable endpoint controls or copy client material into a personal sync service to beat a deadline.
Before arriving, agree on:
- which systems may be accessed remotely;
- where files may be stored;
- whether cellular connections are allowed in the environment;
- how credentials and devices are handled;
- what happens when connectivity fails;
- who authorizes a switch to the fallback path.
Design the software for disconnection
The strongest connectivity plan still assumes failure. Queue writes locally when safe, use idempotent operations, checkpoint long jobs, preserve logs, and make retries visible. A dropped connection should pause or recover a workflow—not duplicate records or leave an operator guessing whether an action succeeded.
For high-risk operations, fail closed and require review after reconnection. Connectivity redundancy cannot justify unsafe autonomous writes.
When upgrading service makes business sense
Calculate what unreliable service already costs: travel to find Wi-Fi, repeated transfers, idle client staff, failed demos, delayed approvals, and engineering time spent reconstructing interrupted work. Compare that with the full recurring cost of the plan and devices.
The best mobile service is the one that removes a measured constraint in the territories where the team operates. If it does not change uptime, travel, or delivery speed, the upgrade is probably not the bottleneck.
Bottom line
Treat mobile connectivity as field infrastructure. Define the workload, test actual locations, understand hotspot terms, protect client data, and make the software resilient to interruption. Carrier selection comes after those decisions—not before them.
Related: Consultant vs Forward-Deployed Engineer, AI Agents in Production, and Own Your AI Infrastructure.